Physics-Informed Neural Networks (PINN) Fundamentals
Theory: putting the equation into the loss
Overview
I hear PINNs can train without data. What do they learn from?
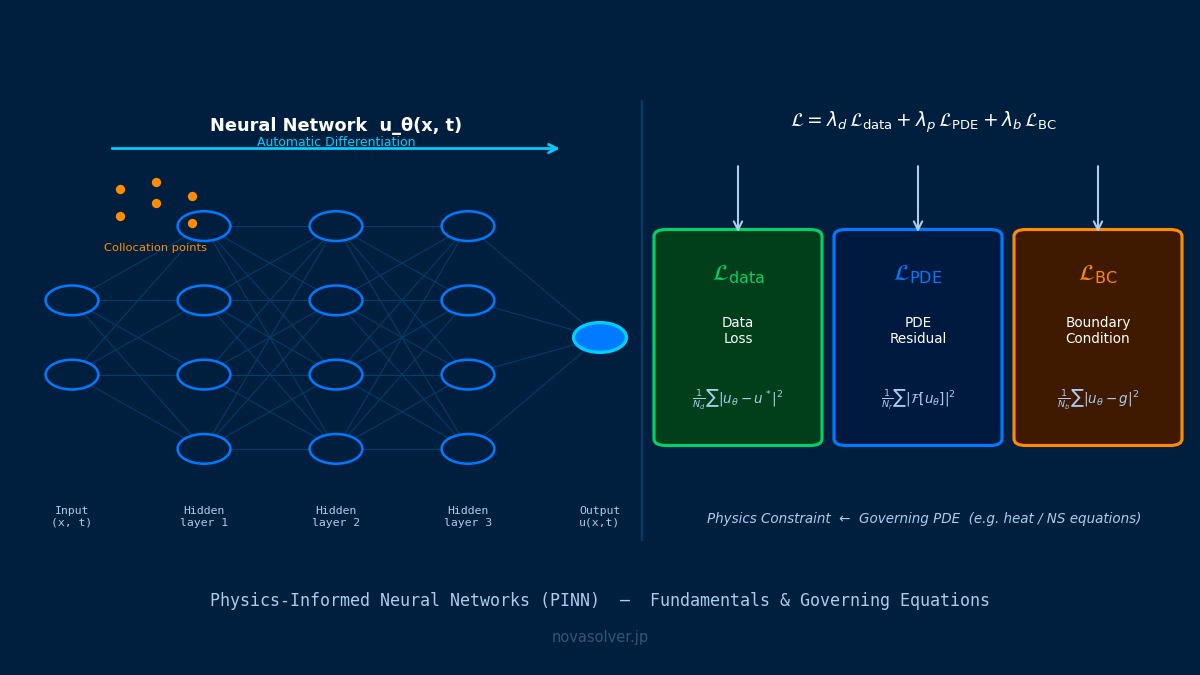
The governing equation itself. An ordinary network learns by reducing the gap to input-answer pairs (data); a PINN instead uses as loss the residual obtained by substituting its function u(x) into the equation. Automatic differentiation computes derivatives exactly, so the residual is evaluated at collocation points scattered through the domain and minimised together with boundary and initial condition errors. Measured data, if any, add another term to the same loss. No mesh is needed and equations and data share one framework. But a falling loss is not the same as a correct solution: results depend strongly on the number and placement of collocation points, how terms are weighted, and how variables are scaled.
The PINN loss function
θ are network parameters, 𝒩 the differential operator (e.g. u″), f the right-hand side, x_i collocation points, g boundary values, λ_b and λ_d weights on boundary and data terms, and L_data the misfit to measurements.
A 1990s idea revived
Solving differential equations with neural networks had already been shown, for example in a 1998 paper by Lagaris and co-workers. It spread as 'PINN' through the 2017–2019 work of Raissi, Perdikaris and Karniadakis because TensorFlow and PyTorch, with automatic differentiation, made writing equation residuals into a loss easy. An old idea became practical almost overnight thanks to better tools.
Worked examples
This is a physics-informed random-feature least-squares example, not a fully trained PINN. It uses 60 hidden units, seed 0, weights/biases in [-8,8], uniform collocation and boundary weight 1. The independent grid has 1,001 points in [0,1]; residuals are RMS, solution error is maximum absolute error. Rounding and random seed can change results.
Example: u″ = −π² sin(πx), u(0) = u(1) = 0 (exact sin(πx))
A one-hidden-layer network of 60 tanh units (a physics-informed random-feature model: hidden weights fixed at random, output layer fitted by least squares), varying the number of collocation points.
| Collocation points | Residual at collocation points | Residual between points | Max solution error |
|---|---|---|---|
| 5 | 6.7×10⁻¹⁵ | 9.3 | 0.75 |
| 10 | 2.6×10⁻¹⁴ | 0.87 | 5.3×10⁻³ |
| 20 | 1.4×10⁻¹⁴ | 1.4×10⁻³ | 4.0×10⁻⁶ |
| 50 | 5.5×10⁻¹⁰ | 7.6×10⁻⁹ | 6.4×10⁻¹² |
With 5 collocation points the residual there is essentially zero (loss minimised), yet between them the equation is not satisfied at all and the solution is far off. When the network has more freedom than there are collocation points, countless answers satisfy just those points.
Training a PINN in PyTorch, the loss falls steadily but boundary values never match. What should I do?
The loss terms are probably badly mismatched in size. The residual term, containing second derivatives, is orders of magnitude larger, so gradient descent pulls almost entirely toward reducing it and the boundary term barely moves. Remedies: increase the boundary weight λ_b; use methods that adapt weights during training by monitoring each term's gradient size; or build the boundary condition into the network output (for example u = x(1−x)·NN(x) guarantees u(0) = u(1) = 0). The last removes the boundary term altogether and is the most reliable. Also normalise input coordinates and outputs to roughly 0–1, or activations saturate and training stalls. After training, check residuals on a fine grid away from collocation points and, if possible, the difference from a known solution or FEM.
Practical workflow
- Decide whether the task is forward or inverse; if FEM suffices, use FEM.
- Nondimensionalise and normalise coordinates and variables so loss terms are comparable.
- Build boundary conditions into the output form where possible; put the rest in the loss.
- Use enough collocation points, more where solutions change sharply, and check residuals at unseen points.
- Verify accuracy against known solutions or FEM before using it for inverse problems or data fusion.
“Watching only the loss curve”
When training a PINN, a falling loss curve is reassuring — but the loss is evaluated at collocation points, so retraining with more points can make the loss jump. That is evidence the earlier solution did not satisfy the equation between points. Logging residuals at unseen points alongside the loss curve exposes such false convergence right away.
Common mistakes
Mistakes and fixes
| Mistake | Effect | Fix |
|---|---|---|
| Too few collocation points | False convergence | Check residual at unseen points |
| Mismatched loss magnitudes | Boundary conditions unmet | Reweight or transform outputs |
| No normalisation | Training stalls | Scale to about 0–1 |
| Using PINNs for routine forward problems | Slow and inaccurate | Choose by purpose |
| No known-solution check | Errors unnoticed | Compare with FEM or analytical |
I'd like to learn related topics.
Related pages include inverse problems with PINNs, PINN heat conduction analysis, DeepONet operator learning and the Fourier neural operator (FNO).
Frequently asked questions
What is a PINN?
A method that represents the solution u(x) with a neural network and trains it on a loss containing the governing-equation residual and boundary and initial condition errors. Derivatives come from automatic differentiation, so no mesh is needed, and measured data can be added to the same loss. Raissi and co-workers set it out systematically in 2019, after which it spread widely.
If the loss is small, is the solution right?
Not necessarily, because the loss is evaluated only at collocation points. For u″ = −π² sin(πx), with 5 collocation points the residual reached 10⁻¹⁴ yet the maximum error was 0.75 and the residual between points was 9.3. With 20 points the error fell to 4×10⁻⁶. Checking residual and error at points not used in training is essential.
Can a PINN replace FEM?
For forward problems (solving with fully specified conditions) FEM is usually faster and more accurate. PINNs shine in inverse problems that estimate material constants or boundary conditions from measurements, in fusing data with models, and in high-dimensional problems. Choosing by purpose is the realistic approach.
References and scope of verification
Numbers are educational reference calculations under the stated assumptions. Sources document theory and setup, not proof that these numerical values were reproduced in each package. Engineering decisions require validation for the actual conditions.
Related Topics
Experience the theory firsthand with the interactive simulator for this field
All Simulators